Service

Data Engineering
& AI Prep

Service Overview

AI doesn't fail because the technology isn't ready. It fails because the data underneath it isn't. Data Engineering & AI Prep is the workstream that fixes that — before you spend a dollar on AI tooling.
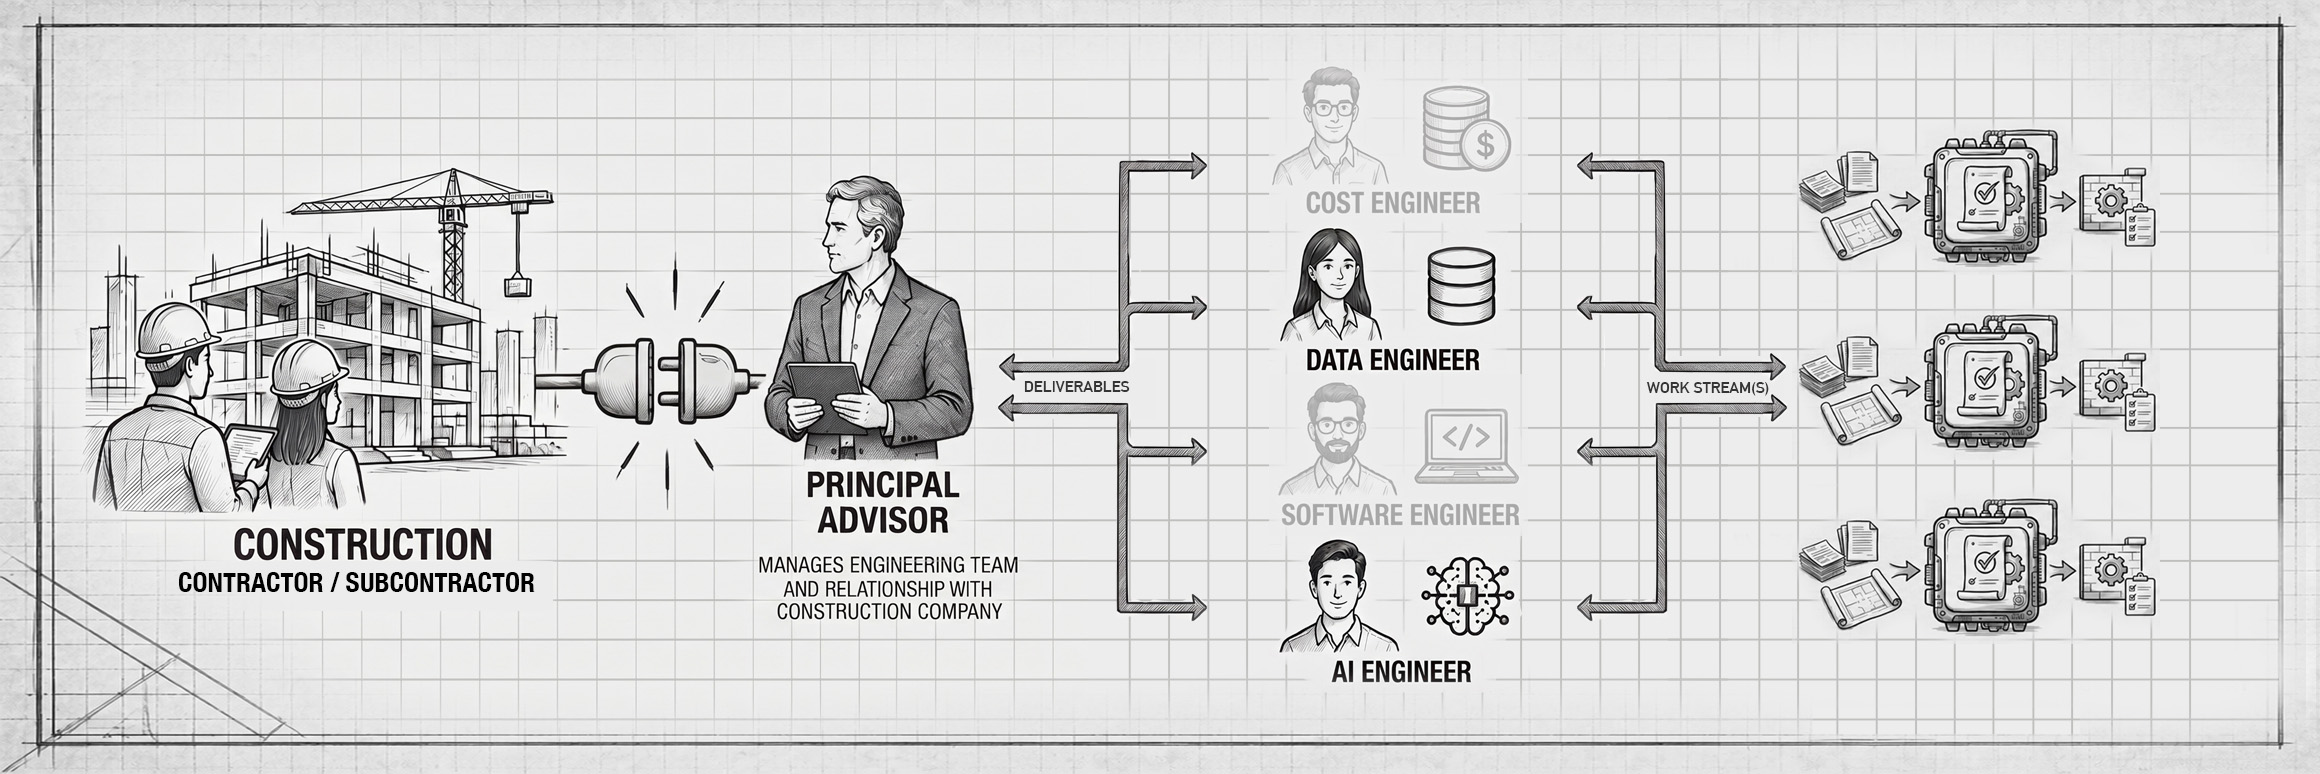
Data Engineering & AI Prep

Most construction companies are sitting on years of project data stored across five or six platforms that don't talk to each other, in formats that don't match, with naming conventions that nobody enforced. That data can't train a model, feed a dashboard, or drive a forecast until someone builds the infrastructure to clean it, connect it, and govern it. That's what this workstream does.

A Red Grey Principal Advisor owns this workstream for the term of your retainer. They staff it internally across data and software engineering. You don't manage the pipeline. You approve the schema, the source-of-truth designations, and the access rules. The artifact — a working, documented, governable data environment — sits in your operation at the end of every month.

Outcomes you can measure. Every month.

Every Engagement begins with a data inventory and audit. At the end of Discovery, you have a written report mapping your current data environment, identifying every gap, and defining the architecture that makes AI viable. Every month after that, the outcome review measures what got built and connected against that map.

🗄️
Clean, Structured Project Data
Project, cost, schedule, and field data in a consistent schema. Source-of-truth designations that everyone respects. No more reconciling three versions of the same job cost report.
🔗
Connected Platform Stack
ERP, PM platform, accounting, and field tools sharing data through defined pipelines. Manual re-entry eliminated at the points where it costs the most time.
📊
Reporting That Reflects Reality
Dashboards and reports built on live, governed data — not exports someone ran last Tuesday. Numbers your PM, your principal, and your finance lead can all trust.
🤖
AI-Ready Data Foundation
Data quality, access controls, taxonomy, and source-of-truth designations in place before any AI tool is deployed. No shortcuts that turn into six-month cleanup projects later.
🔒
Access Control & Governance
Role-based access to data assets. Audit trails on who touched what. Data quality rules enforced at the point of entry, not discovered after the damage is done.
📋
Data Documentation
A data dictionary your team can actually use. Schema documentation that doesn't live only in one engineer's head. Onboarding new staff onto your data environment becomes a 30-minute exercise, not a month of tribal knowledge transfer.

Common workstreams under this service.

These are the most common workstreams we build under Data Engineering & AI Prep. Discovery defines which ones are highest priority for your specific operation and the AI use cases you're targeting.

Data Inventory & Audit ⚙
→ Map every data asset in the operation.
→ Where it lives, what format it's in, who owns it, how it's used, and how it connects to everything else.
→ Identify duplicates, gaps, and quality issues.
→ Deliver a written inventory that becomes the foundation of the data architecture.
Data Pipeline Architecture & Build ⚙
→ Design and build the pipelines that move data between your systems reliably and on schedule.
→ Define the transformation rules, the error handling, and the monitoring.
→ Deliver a pipeline your team can operate and extend without calling us every time something changes.
Master Data Governance Framework ⚙
→ Define the source-of-truth for every critical data entity.
→ Project, cost code, vendor, employee, equipment.
→ Set the naming conventions, the ownership rules, and the update protocol.
→ Document it so it survives staff turnover.
Platform Integration Layer ⚙
→ Connect your ERP, PM platform, accounting system, and field tools through a documented integration layer.
→ API connections where they exist.
→ Extract-transform-load pipelines where they don't.
→ Data flowing in both directions where the business requires it.
AI Readiness Assessment & Roadmap ⚙
→ Evaluate your data environment against the specific requirements of the AI use cases you're targeting.
→ Cost forecasting, document processing, field reporting, estimating automation.
→ Deliver a scored readiness assessment and a sequenced roadmap that tells you what to fix before you deploy what.
Reporting & Analytics Foundation ⚙
→ Build the reporting layer on top of the governed data environment.
→ Dashboards your PM runs daily, not quarterly.
→ KPIs your principal reviews monthly, not after accounting closes.
→ Alerts that surface variance before it becomes loss.

From the first call to retained delivery. Here is exactly how it works.

Every engagement follows the same sequence. No surprises. No ambiguity about what you're agreeing to before you agree to it.

01
Scoping Call — 30 Minutes
You describe the challenge. We ask the questions that tell us where the problem actually lives. By the end of the call we tell you which workstream addresses it, what Discovery looks like for this specific problem, and what the first 30 days produce. You leave with a verbal scope and a clear picture of what comes next. No pitch deck. No follow-up sales cycle.
02
Mutual Non-Disclosure Agreement
Before we review any project data, financials, or internal systems, both parties execute a Mutual NDA. This is a standard two-way confidentiality agreement — it protects your data and our methodology equally. We send it, you review it with your counsel if needed, and we execute before anything substantive is shared. Typical turnaround is one to two business days.
03
Master Service Agreement
The MSA governs the overall relationship — intellectual property ownership, liability, payment terms, dispute resolution, and termination provisions. It is executed once and covers every Statement of Work issued under it. We provide the standard Red Grey MSA. You review it, propose any changes, and we agree before any work begins. The MSA is the legal foundation. The SOW is the operational scope.
04
Discovery Engagement — 30 Days
Month one is always Discovery. For Data Engineering, Discovery is a 30-day structured inventory and audit of your data environment. We map every platform, every data flow, every manual handoff, and every re-entry point. We assess data quality across your most critical assets — cost, schedule, project, and field data. We evaluate your current reporting against the business questions it's supposed to answer. At the end of 30 days, we deliver a written findings report: a complete map of your current data environment, a gap analysis against the AI and reporting use cases you're targeting, and a prioritized architecture roadmap. The Discovery Engagement is priced as month one of your retainer. It is not a separate fee.
05
Statement of Work
The SOW is issued after Discovery findings are reviewed and accepted. It defines the specific workstreams to be delivered, the success metrics for each, the systems in scope, the communication cadence, and the term. It is signed before month two begins. The SOW is not a proposal — it is the execution document built directly from the Discovery findings. If the Discovery findings don't support a particular workstream, it doesn't appear in the SOW.
06
Retained Term — Monthly Delivery
The retainer runs on a monthly cadence from SOW execution. Weekly working sessions move each workstream forward. Monthly outcome reviews measure what moved against the baseline established in Discovery. Every month produces a working artifact — a tool, integration, workflow, or process that exists in your operation. Your Principal Advisor signs off on every deliverable. You approve outcomes and success metrics. You do not manage the engineering work.
07
Scaling Engagements — Scope Change Engagement
The number of concurrent Engagements is set at contract signing and fixed for the term. If your priorities shift mid-term and you need to add or remove a workstream, that requires a Scope Change Engagement — a structured rescoping process that produces updated findings, a revised SOW, and a clear transition plan. The Scope Change Engagement is priced at your original Discovery rate and billed in addition to your current monthly retainer. Changes take effect at the start of the next engagement cycle after the Scope Change Engagement is complete. At contract renewal, your Engagement count can be adjusted with no Scope Change Engagement required.
08
Runbook & Adoption Handoff
Every workstream closes with a Runbook & Adoption Pack. The runbook documents how the tool or workflow operates, who owns which step, how data quality is maintained, and how to know it is being used. The adoption pack covers staff training, role-level instructions, and what a healthy versus degraded state looks like. The handoff is documented, reviewed, and signed off before the Engagement is marked complete. This is not a PDF filed away. It is the operating manual for the artifact we built.

How we access your systems. What we touch. What we don't.

This work requires access to your systems and data. We take that access seriously. Here is exactly how it works.

What We Access
Access to your ERP, accounting platform, PM software, and field data tools. We typically need read access to data exports, API documentation, and schema definitions during Discovery. Build phases may require write access to specific systems — pipelines, data warehouses, or integration middleware — scoped and documented in the SOW before anything is connected.
How Access Is Granted
We request the minimum permission set required for the workstream in scope. Where possible, we use read-only credentials for data review and analysis work. Write access is requested only for the specific systems we are building into. We do not request admin or owner-level access unless the workstream explicitly requires it — and if it does, that is documented in the SOW and requires your written approval before access is granted.
Credential Management
Credentials are stored in a dedicated password manager, never in email or shared documents. Access is provisioned to the named Red Grey engineer assigned to the workstream. Access is revoked at the end of the Engagement or immediately on request. We do not retain credentials after an Engagement closes. If you prefer to provision temporary access per working session, we accommodate that without adding friction to the delivery cadence.
Data Handling
Your data does not leave your systems unless a specific integration or export is part of the workstream scope. Working files used during analysis are stored in a Red Grey client workspace, not in personal accounts or shared drives accessible outside the Engagement team. The NDA governs confidentiality. The MSA governs data ownership — your data is yours. We build on it. We do not retain it.
Communication Security
All client communication runs through a dedicated Slack workspace. Red Grey maintains its own workspace with per-client channels. Your team connects via Slack Connect — you see your channel only, not any other client's. Sensitive documents are shared via a secure link, not as email attachments. We do not use SMS for anything substantive. We do not discuss project data on open channels.
Access Offboarding
When an Engagement ends — whether at term, by mutual agreement, or by early termination — we initiate access offboarding within 24 hours of the final engagement date. All credentials are revoked, all working files are either returned to you or deleted per the offboarding checklist in the SOW, and a written confirmation is issued. You do not need to chase us for this.

Every engagement begins with a 30-day Discovery.

Discovery is not a consulting engagement you buy hoping it leads somewhere. It is month one of a retained workstream. It produces a written findings report. It becomes the foundation of your SOW. If the findings don't support moving forward, you have a clear picture of why and what to do about it — and you are not locked into anything.

Data Engineering & AI Prep — Discovery Engagement

30 days. A complete map of your data environment and what it will take to make AI viable.

The Discovery Engagement for Data Engineering covers four areas: data inventory and quality audit, platform connectivity and integration gap analysis, source-of-truth and governance assessment, and AI readiness scoring against your target use cases. We review every platform in your stack, map every data flow, and assess quality at the field level. At the end of 30 days, you know exactly what you have, what's broken, what's missing, and what to build first.

Written findings report — complete data environment map and quality assessment
Platform connectivity diagram — what connects, what doesn't, and what it costs
AI readiness score across six dimensions with gap analysis
Source-of-truth inventory — what's authoritative, what's redundant, what's missing
Prioritized architecture roadmap — what to build in what order and why
Baseline metrics — data quality scores and pipeline coverage we'll measure against monthly

Discovery-Only Hold Policy. If you complete a Discovery Engagement and do not immediately convert to a retainer, your findings remain valid for 90 days. If you return within that window, you convert directly to a retainer with no additional Discovery required. After 90 days, a new Discovery Engagement is required before a retained term begins.

Not sure which service to start with? The scoping call is the right place to figure that out. Tell us what you're dealing with and we'll tell you where to start.

Ready to build the data foundation your operation needs?

30-minute scoping call. Tell us what AI use cases you're targeting and we'll tell you where your data stands.